Brief, mostly signal
Hamel Husain compares decision models for LLM eval failure detection
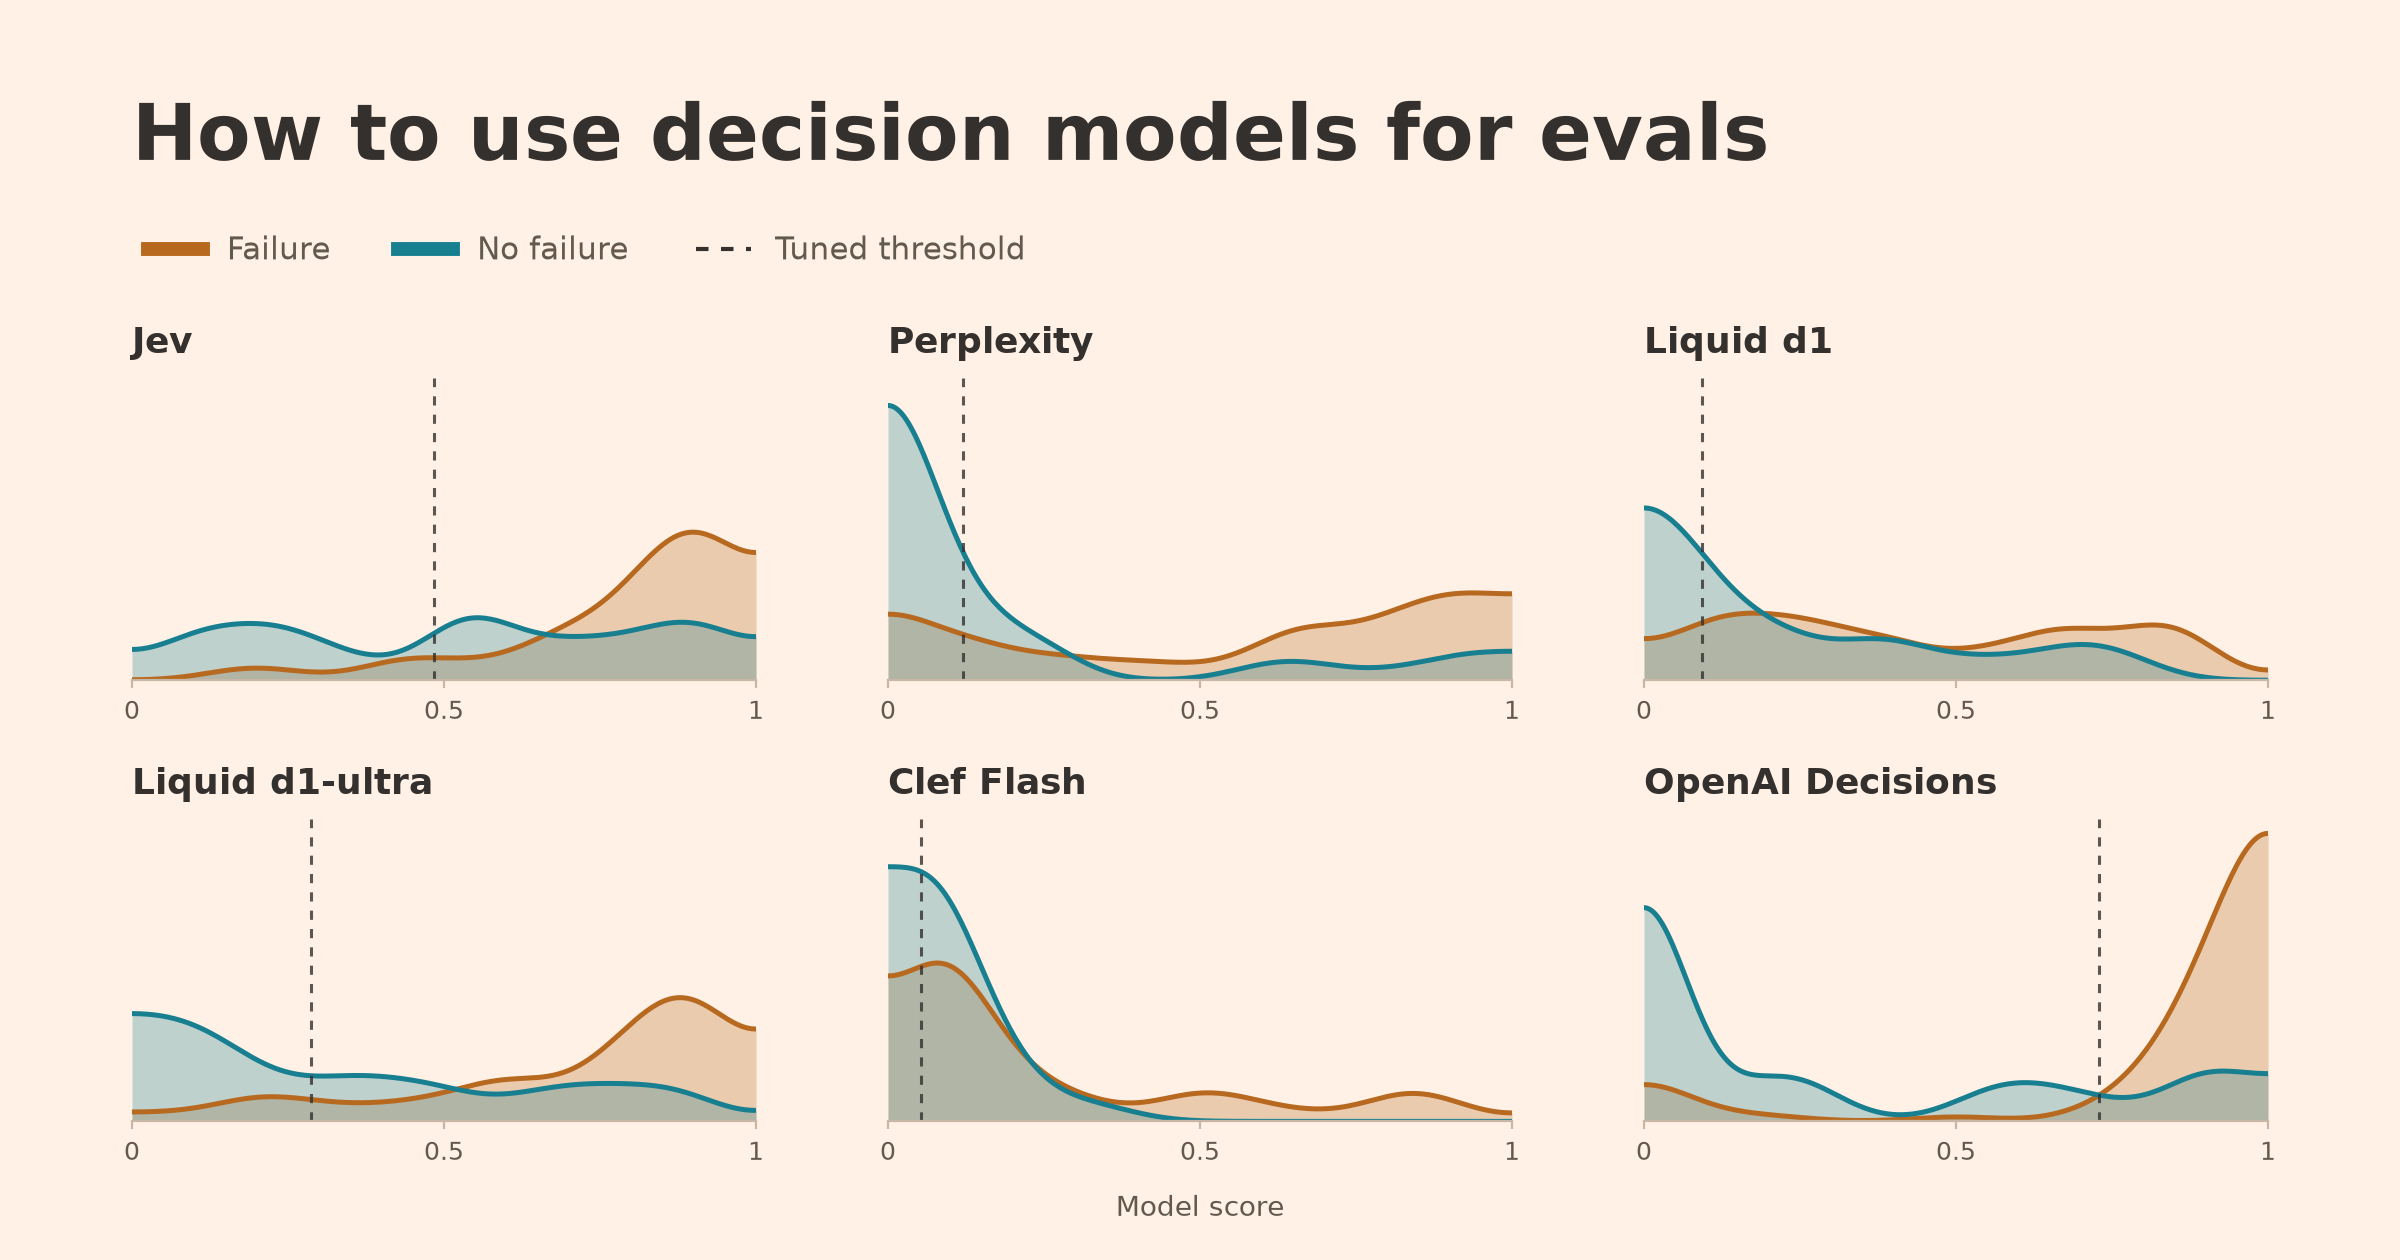
Tested five models on 100 leasing-agent traces. He argues the default 0.50 threshold should be tuned, with cost and calibration checked.
Brief, mostly signal
Tested five models on 100 leasing-agent traces. He argues the default 0.50 threshold should be tuned, with cost and calibration checked.
Hamel Husain's post compares decision models (Jev 1.13, Perplexity Decider, Liquid d1, Cloudflare Clef Flash, OpenAI Decisions) for LLM eval failure detection on 100 leasing-agent traces, arguing the default 0.50 threshold should be tuned and cost and calibration checked.
Actionability rated medium.