Brief
Trust layer as a governance control plane for agentic AI
SDxCentral argues agents need a control plane for governance, security and accountability. The piece is conceptual, with no product, version or dated facts.
- Signal
- 37
- Facts
- 11
- Hype
- 17
Topic
69 cards
Brief
SDxCentral argues agents need a control plane for governance, security and accountability. The piece is conceptual, with no product, version or dated facts.
Brief
The arXiv paper chooses among single-round, multi-round and agentic routing with one policy. It reports 61.4 percent average accuracy, an 11.03 percent relative gain over the strongest baseline.
Hype watch
The Japanese roundup cites single-source claims of 30,000 daily merges and a GKE Agent Substrate launch. Primary confirmation is missing.
Brief
Agent Skills, Open Responses, OpenEnv and OpenSandbox joined the foundation on October 22. The additions bring the total to 10 hosted projects.
Brief
Of 300 leaders surveyed, 77 percent saw negative consequences. Only 51 percent monitor agents in real time and 42 percent keep a central agent registry.
Brief
The heise listing covers GitHub Copilot, spec-driven development and TDD, capped at 16 participants. It is a course listing, not a news event.
Act on this
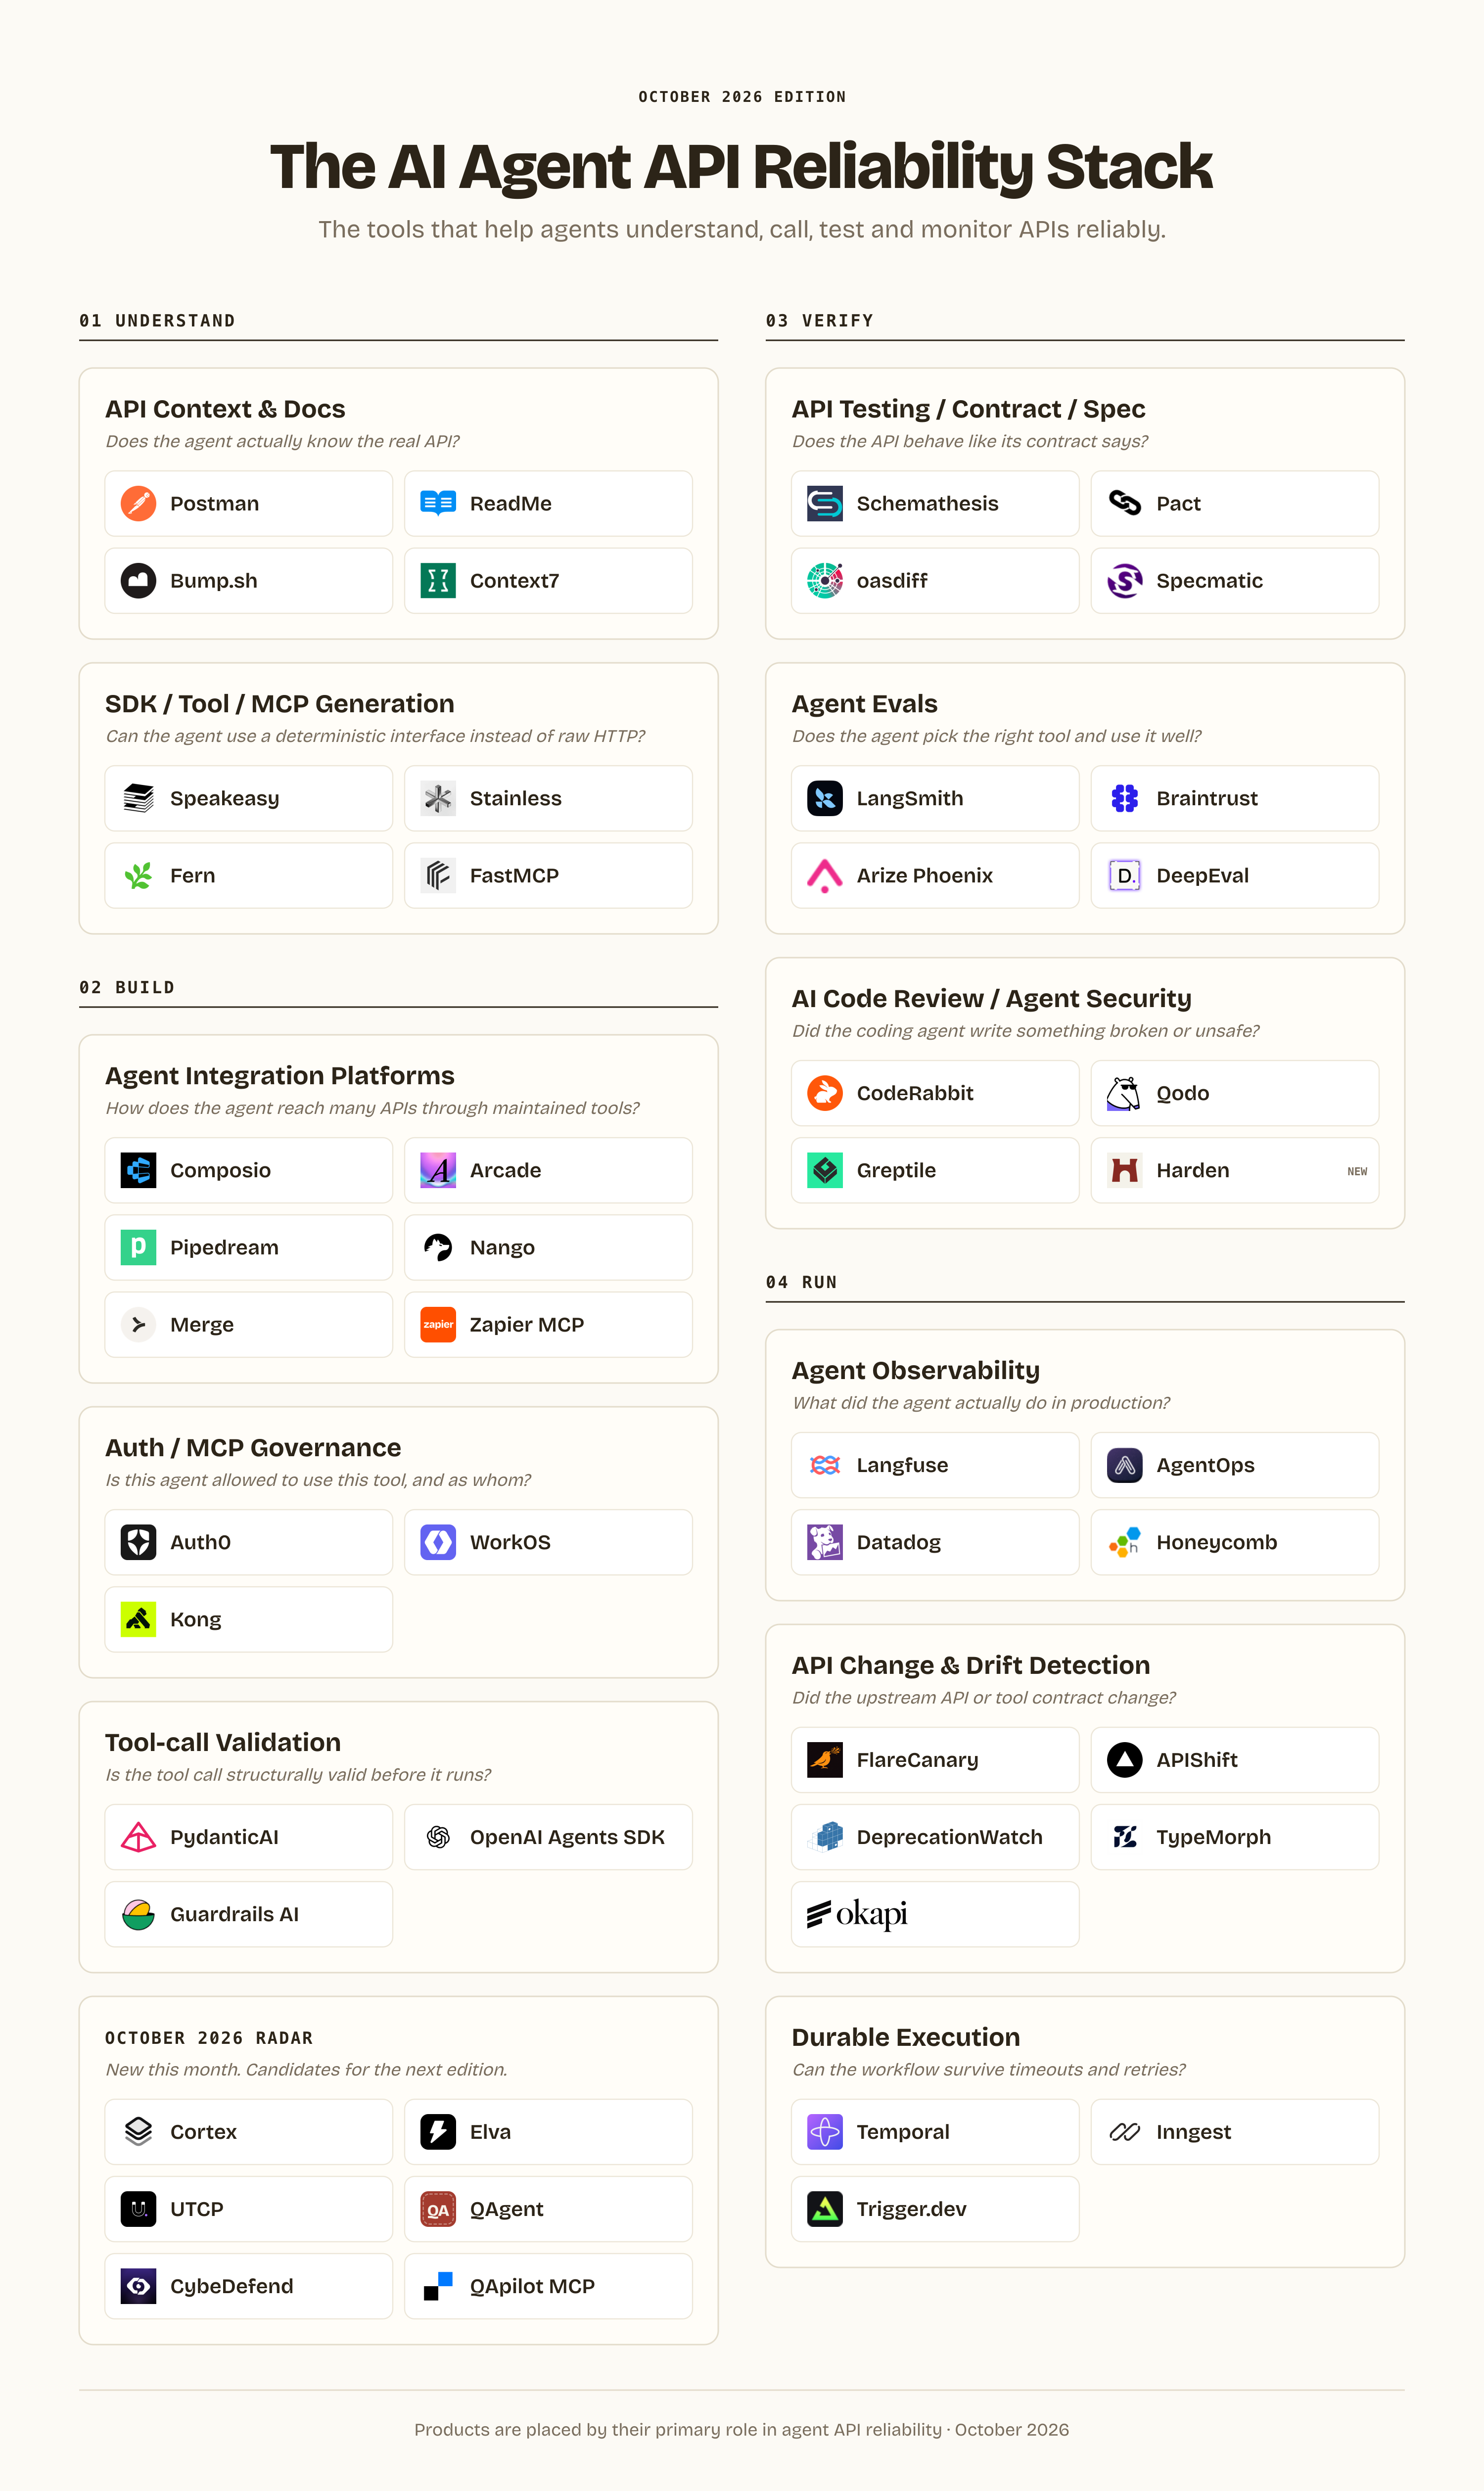
Use the Understand, Build, Verify and Run map to check your agent's API calls against the tools it lists.
Brief
The t3n piece makes a general case for agent harnesses. The cached text is boilerplate, so no specific claims could be checked.
Brief
The opinion piece argues the key security question is whether design, security and organizational frameworks can limit delegated authority and prove those limits. It cites Hamad and Steinhorst research.
Brief
A Reddit user is designing a local, human-gated content pipeline and asks which Claude Code or Cowork subagents, plugins and MCP servers work in practice.
Brief
A Product Hunt launch that connects coding sessions to PRs, issues and quality. Connector details and availability are thin in the cached text.
Brief
A Hacker News user says a small connector let local Claude or Codex patch servers without SSH, firewalls or VPNs. It is a single anecdotal report.
Brief
Bits is pitched as a personal agent that gets things done. The cached listing is thin, and the open-source claim is not confirmed.
Brief
A Show HN repo of skills lets Claude, Cursor or Hermes agents generate UGC, ad videos and product photos. The cached page shows little beyond the repo description, so the details are unverified.
Brief
An arXiv paper proposes five capabilities for multimodal embodied agents. Across 64 benchmarks only 5 assess Anticipate and 3 assess Verify.
Brief
The method cuts repeated tool-call loops, lowering Qwen3-8B loop share from 57.3% to 6.1% on CodeGym under compression. The paper was published October 14.
Brief
The arXiv paper AW-0 reports gains over VLA and WAM baselines on RoboTwin 2.0. No models or code are linked yet.
Brief
The method reaches 0.801 utility on SkillTransferBench versus 0.723 with no skill. A variant uses 61.7% fewer educator tokens, and the dataset is on Hugging Face.
Brief
The paper reports better generalization to unseen white-box and external black-box harnesses. It is a research abstract with no linked code release.
Brief
An opinion piece says agentic systems need planning, monitoring and revision, and that goals are often underspecified. It has no concrete release or deadline.
Brief
An arXiv paper where a meta-agent co-evolves a user simulator, environment and RL setup. It reports 14.7 to 15.0 percent overall gains and up to 36.7 percent on ColBench.
Act on this
Copy the pattern of scripted polling plus Claude matching, and keep the decisions with the human.
Act on this
Install the sem-cli binary with brew to give agents entity-level diffs instead of raw line diffs.
Act on this
Plan for an always-on Mac, Tailscale and an Apple Developer membership before you copy it.
Act on this
Download the Q4_K_M or Q8_0 GGUF build to test subagent orchestration locally.
Act on this
Keep tool-result text plain, and check domains with an MX DNS lookup in code.
Act on this
Run the Apache 2.0 local demo with Python 3.12 and uv to test self-rewriting harnesses.
Act on this
Test the beta if you coordinate sub-agents, since Claude writes an orchestration program that runs server side.
Brief
A Nagarro commentary says to measure real consumption on repeated typical tasks. It is advice, not a release.
Brief
A pre-specified study on Terminal-Bench 2.1 found pass rates stayed at 73.0% in both arms. The controller was poorly calibrated and never chose to abandon a run.